Leading-edge Blackwell GPUs racked, cooled, and serving real workloads today. Skip the AWS waitlist. Talk to a real engineer. Pay by the hour or by the month - no quote-walls.
SPUR Compute is fielding NVIDIA B300 SXM6 chassis in our Waterloo data centre - the most powerful production GPU NVIDIA ships, with 288 GB HBM3e per GPU and 2.3 TB per node. Native FP4, NVLink-5, InfiniBand-ready. Hardware is racked and serving paying customers; no waitlist, no months-long queue.
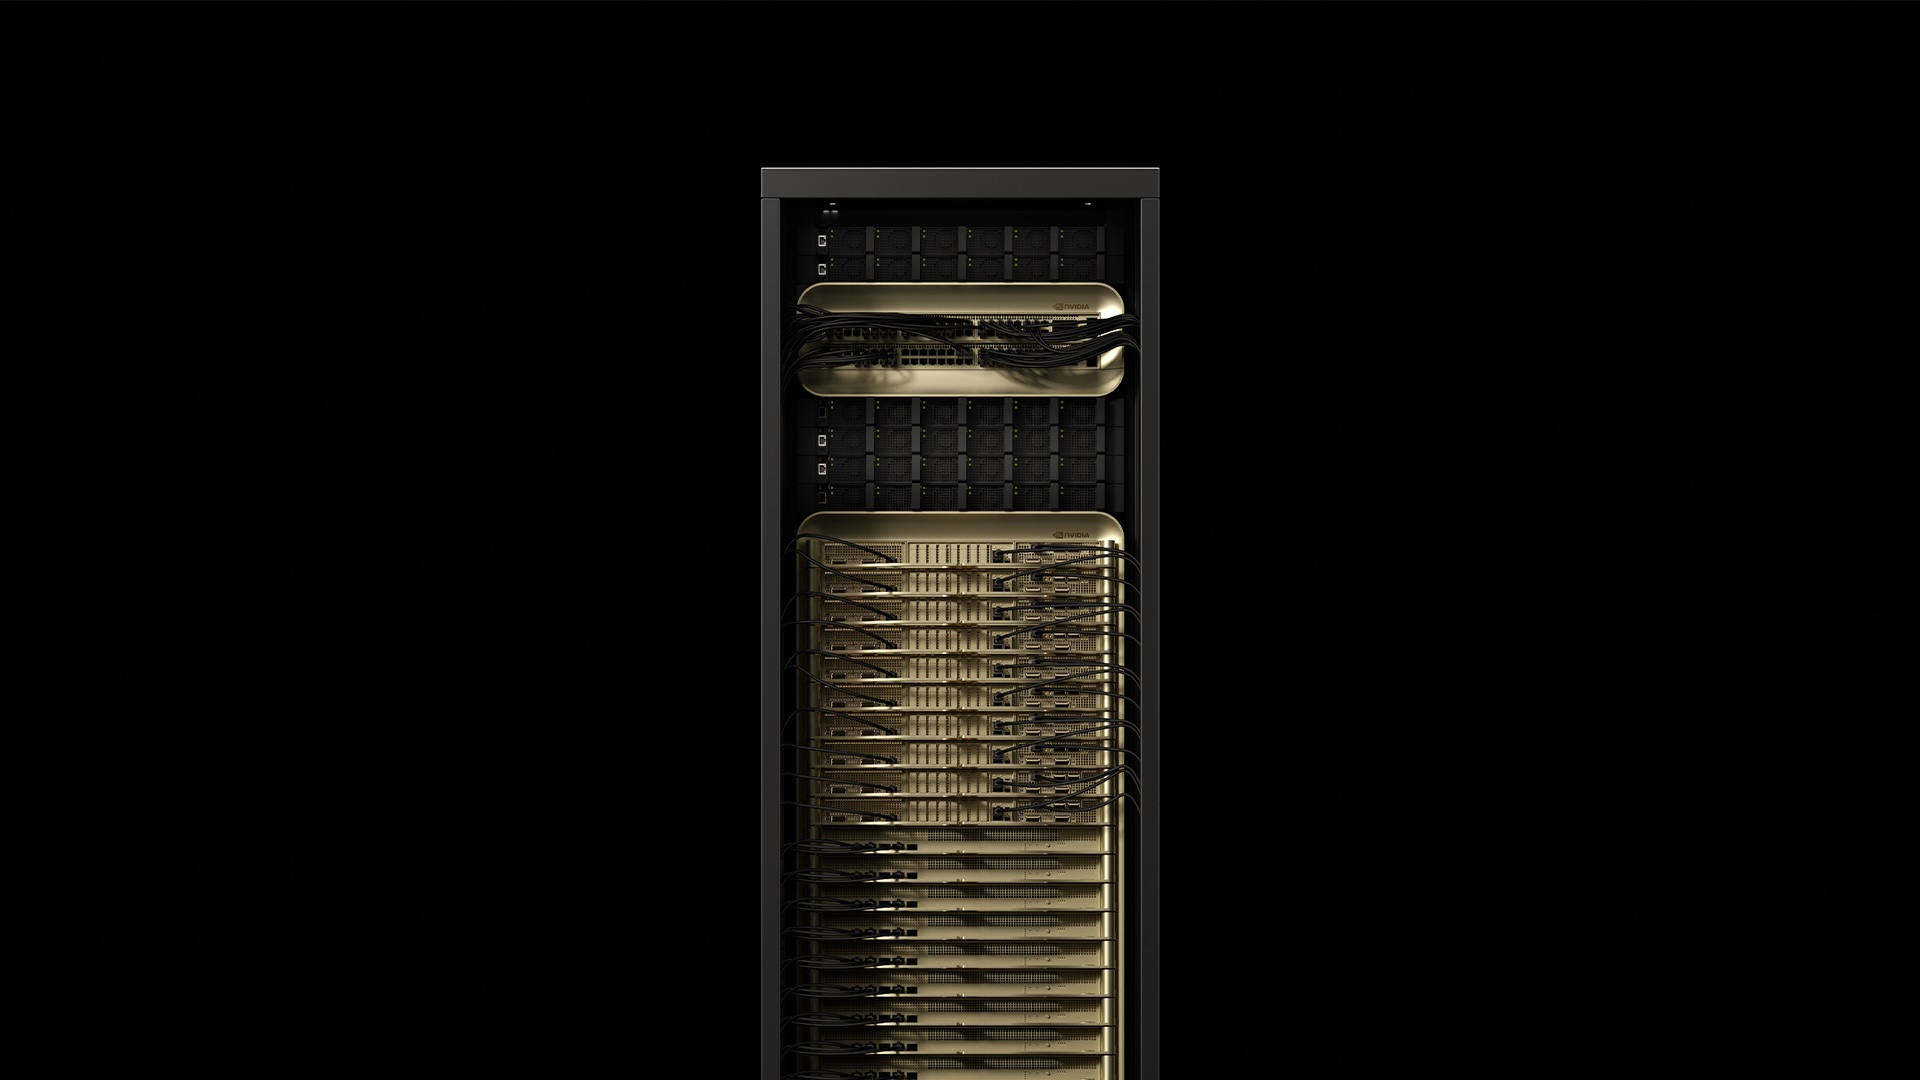
GLM 5.3 (MoE, 1M context) is hosted in Canada and serving inference today via an OpenAI-compatible API. Frontier-class reasoning and native tool-calling without paying frontier-cloud markup, and without sending your prompts across the border. Point your existing SDK at ai.spuric.com and switch.
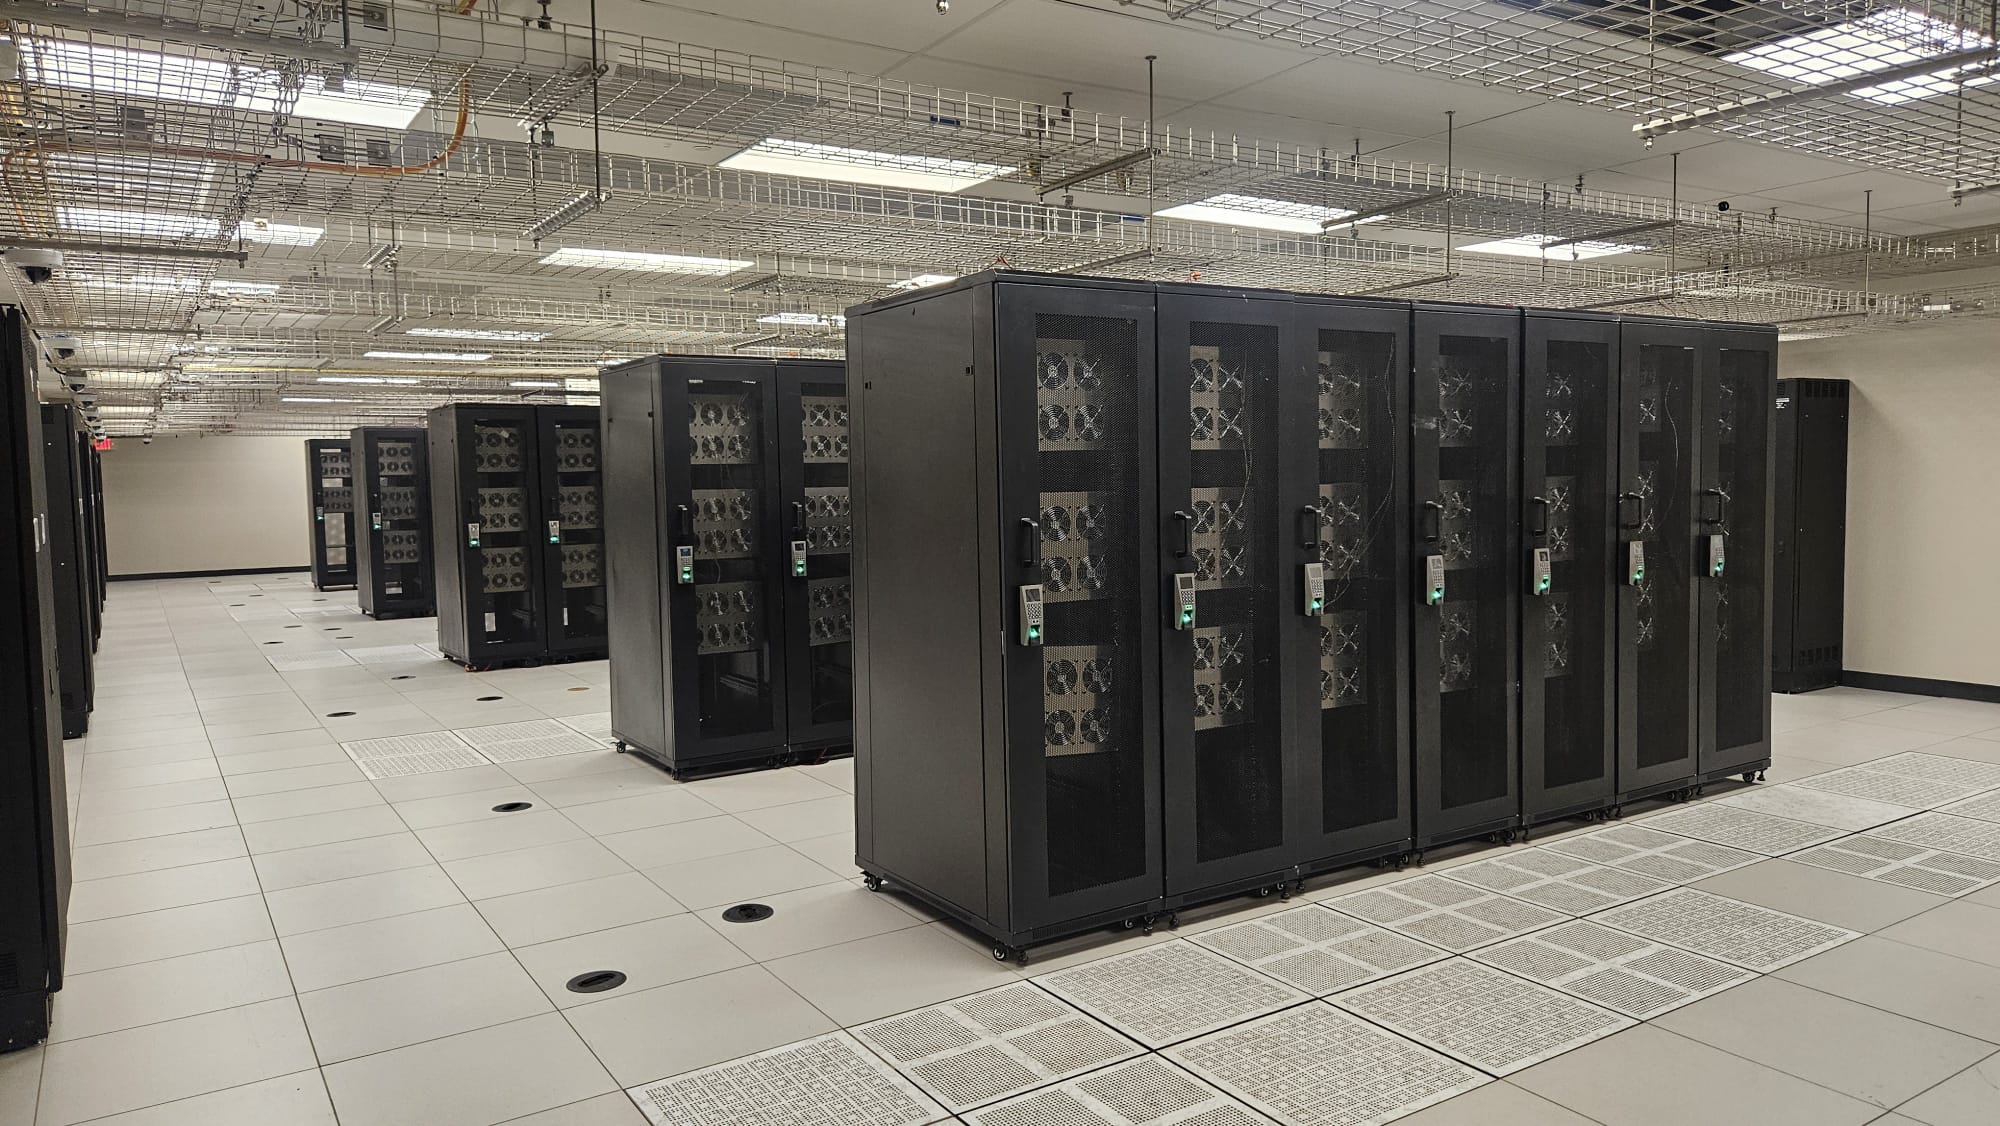
B300 capacity fits the workloads that used to require a hyperscaler contract: large-model training and fine-tuning, high-throughput production inference, scientific simulation, and frontier research. SPUR engineers help you size the cluster, pick the framework, and ship.
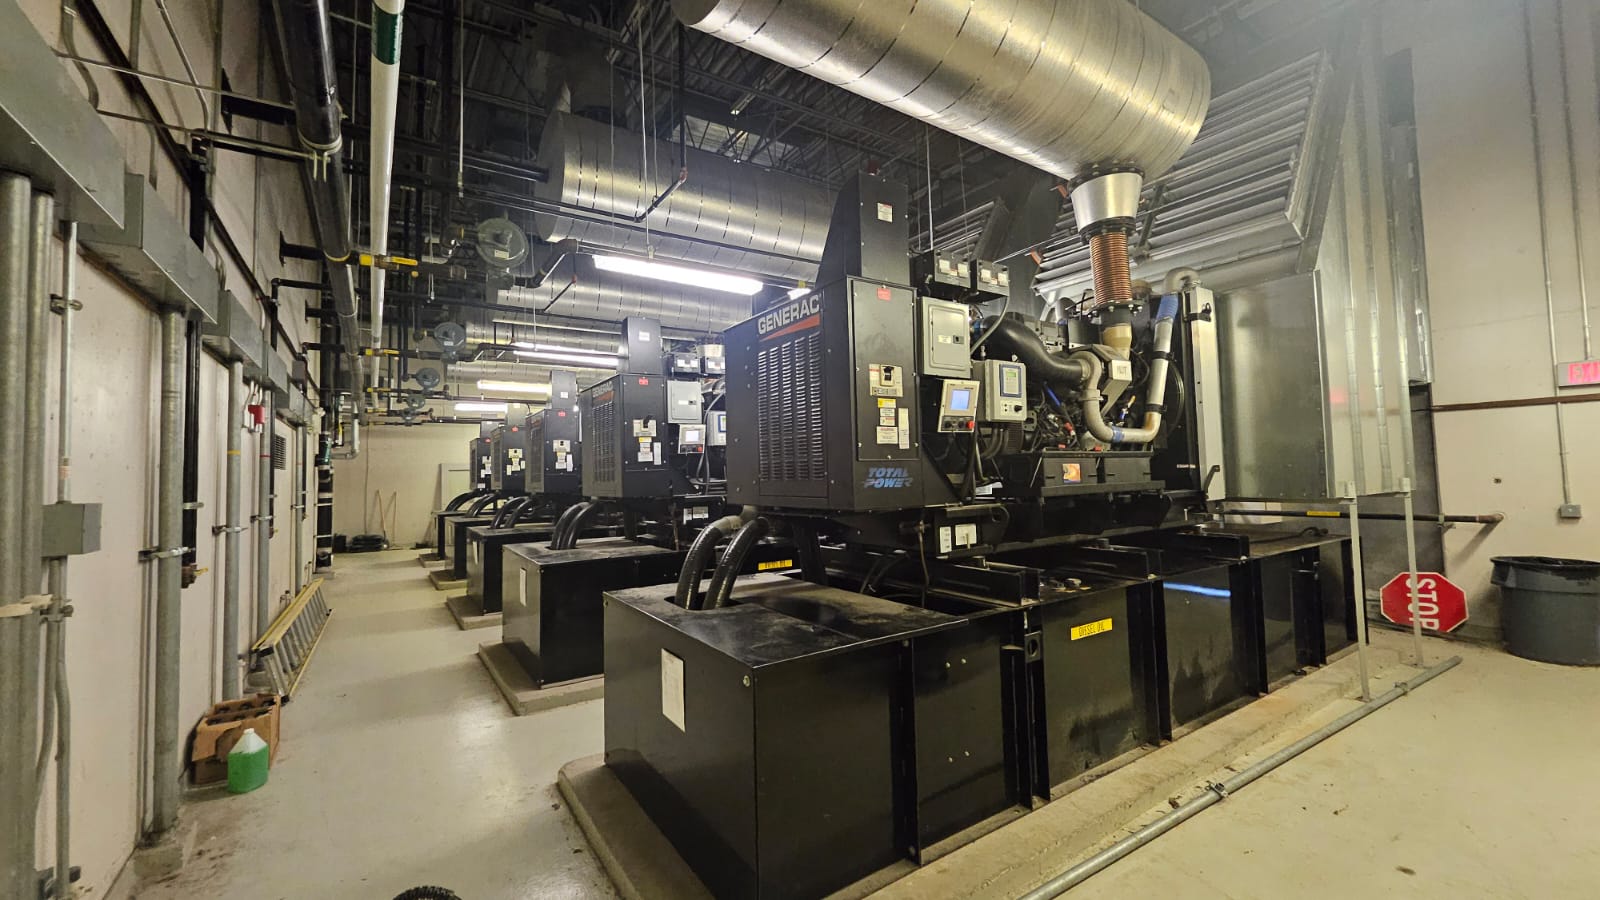
SPUR Compute is operated end-to-end inside Canadian jurisdiction. No US CLOUD Act exposure. No cross-border transfers. PIPEDA-aligned by default and engineered to SOC 2, PCI-DSS, and ISO 27001 controls. Hardware you can walk up and touch, run by engineers who answer the phone.
Try GLM 5.3 in your browser, or talk to a SPUR engineer about a dedicated allocation - hourly, monthly, or annual contract.